Application Support Service: The Key To Reliable Business Apps In 2026
📍 New York
🕐 1 hour from now
👁 5 views
USD 0
Description
Reliable business applications depend on more than software quality. They depend on how people respond when a release changes a workflow, an incident interrupts work, or an update alters a familiar process. That human side of application reliability is easy to underestimate. KPMG's research on resistance to organizational change found that 55.4% of surveyed organizations used staged rollouts or pilot programs, while 54.1% relied on clear communication about why a change was happening. KPMG research on resistance to change Those figures matter for application teams because a technically successful deployment can still create operational problems when users don't understand the new process or support teams aren't ready for the resulting questions. Reliable applications in 2026 therefore require a support model that covers system health and the way people experience change. Application reliability now includes the way people experience change An application may remain online while its users struggle to complete normal work. A modified approval screen, changed permission model, new integration, or revised data field can disrupt established habits even when the release passes technical testing. This is why application support has to look beyond uptime. Teams need to watch incident volume, failed workflows, user questions, access problems, release effects, and recurring trouble after each change. Calance describes its application support model as covering incident management, monitoring, data workflows, controlled releases, documentation, user access, and stakeholder reporting. The important point is that reliability has 2 sides. Engineers need evidence that the system works, while users need to know how their work has changed and where to get help when something doesn't behave as expected. Resistance often begins with workload and unclear expectations Employees who hesitate after an application change aren't necessarily rejecting the technology. They may be protecting a workflow they already understand, dealing with a heavy workload, or trying to avoid an error while instructions are unclear. KPMG's study gives useful context. Along with staged rollouts and clear communication, 48.6% of respondents said leaders actively listened to employee concerns, while 41.9% provided skill-building sessions connected to organizational changes. Only 9.5% said their leadership made no attempt to manage resistance. That suggests adoption work should begin before deployment. Teams need to identify who will be affected, what tasks will change, which groups face the greatest learning burden, and where temporary productivity losses may occur. Communication should explain what changes in the employee's work General announcements rarely prepare people for a changed application. Users need information tied to their own tasks. A finance employee may need to know how an approval route changed. A field worker may need revised mobile steps. A manager may care about reporting changes, while the service desk needs error conditions and escalation paths. Communication should therefore answer practical questions: What changes on the release date? Which existing steps remain the same? Where should users report a problem? What happens if the new process fails? This also reduces avoidable support traffic. When users understand expected behavior, support teams can separate genuine defects from questions caused by unfamiliarity. Training works better when it matches roles and real tasks Training should reflect what each group actually does inside the application. A 2024 scoping review of electronic health record training found that role-specific training was an important consideration and examined implementation barriers and supporting factors across inpatient nursing environments. 2024 review of role-specific EHR training The same principle applies outside healthcare. Users who approve transactions need different instruction from administrators who configure access. Support engineers need diagnostic information that ordinary employees don't need. Training should also happen close enough to deployment that users can apply it. Documentation, short demonstrations, test environments, and role-specific practice can reduce the gap between hearing about a change and performing the changed task. Implementation support should continue after the release date The first days after deployment reveal problems that testing can't always predict. Real workloads expose unusual user paths, permission gaps, integration failures, and confusing process changes. This is where Application Maintenance and Support Services can provide the operational layer needed after a release. Monitoring and incident handling help teams detect technical trouble while feedback from users shows where adoption is breaking down. Teams also need Application Support and Maintenance Services when application ownership moves from a project team into normal operations. Calance's transition process includes discovery, documentation, stabilization, shadowing, and ongoing operation, which helps preserve knowledge during that handoff. Effective Applications Support Services should connect user reports with technical evidence. A spike in tickets after a release might point to weak training, a confusing interface, a faulty dependency, or several different issues that require separate responses. An Application Support Service also needs controlled change practices. NIST guidance treats incident response as part of wider organizational risk management and stresses preparation, detection, response, and recovery across operations. NIST incident response guidance Reliable change requires measurements from both systems and users Application teams need measures that show whether technical performance and user adoption are moving in the right direction. Useful operational measures include availability, incident counts, mean time to resolve, failed deployments, repeat problems, access requests, and user satisfaction. Support teams should also watch ticket categories after major releases because a sudden rise in one type of request may expose a training or workflow problem. Software delivery data can provide another signal. A Google Cloud case study reports that SiteGround reduced its change failure percentage from 5% to 0.75% and brought failed-deployment recovery time down to 8 minutes while changing its delivery practices. Google Cloud SiteGround case study Those numbers shouldn't be treated as universal targets. They show why teams need their own baseline so they can judge whether releases are becoming safer and recovery is getting faster. The first sign of adoption is normal work returning without extra help A change begins to take hold when people can complete the affected work without relying on temporary workarounds or repeated support requests. That signal is more useful than simply confirming that training was delivered. Teams should look for falling repeat-ticket volume, stable task completion, fewer access problems, lower escalation rates, and feedback showing that users understand the changed workflow. Support should continue until those signals stabilize. A release is technically complete when the software is deployed, but the operational change is established only when the application becomes part of normal work again
Similar Ads
 📷 2
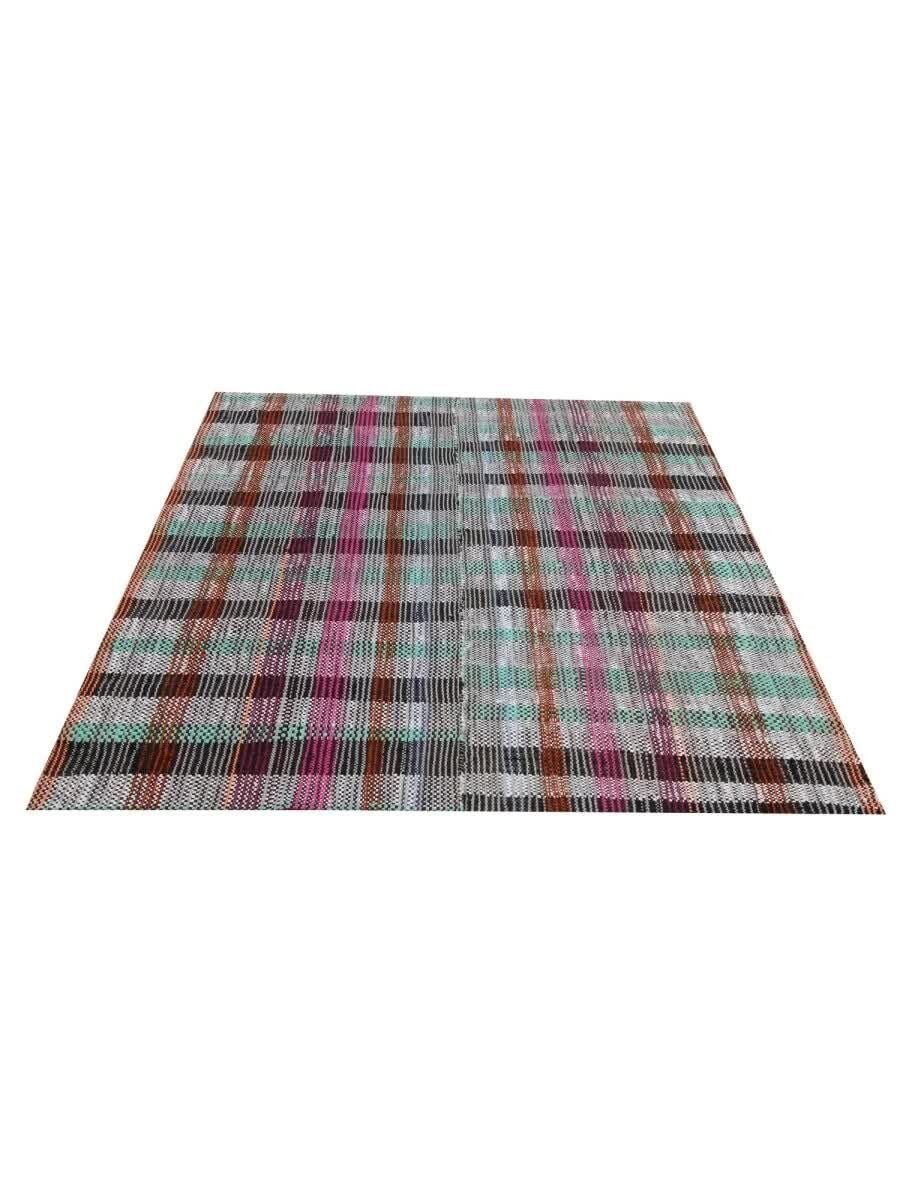
USD 440, 8x9 Persian Kilim Area Rug
USD 0
USD 30, Best Graphic Tees & Hoodies For Style & Inspiration – Pass The Positive
USD 0
Handmade Crochet Animals | Cute Crochet Toys & Gifts
USD 0
USD 340, Mid-Century Modern Stainless Steel Post Mount Mailbox - Spira Mailbox
USD 0
USD 133, Luxury Stretch Denim | High Waisted Wide Leg Jeans – Chic Life
USD 0
Create Outdoor Comfort With A Pergola Contractor
USD 0
🛡️ Stay Safe
- ✓ Meet in a public place
- ✓ Inspect before paying
- ✓ Never pay in advance